DATA SCIENCE
Stunting Risk Classification
A classification project that predicts stunting status based on demographic and growth features.
View on GitHub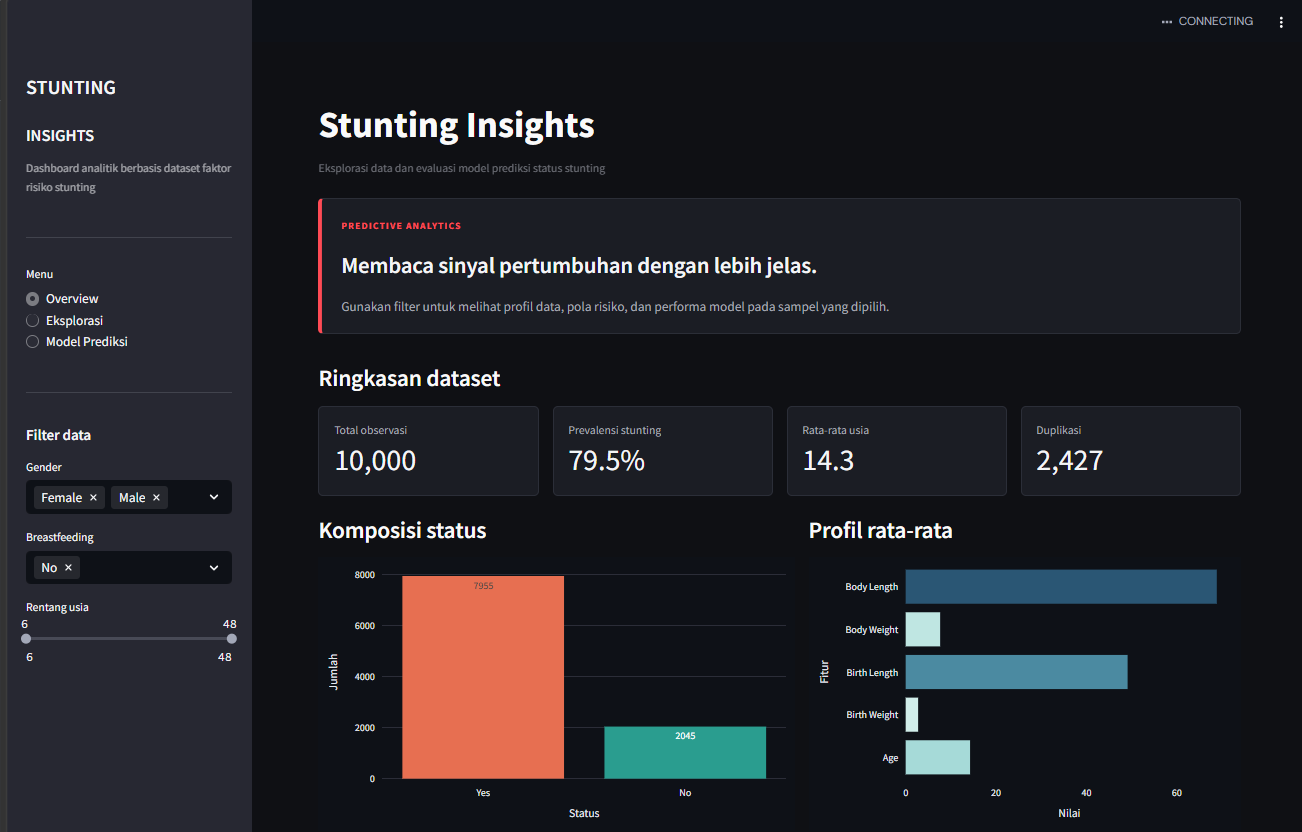
My Contribution
- Performed exploratory data analysis on demographic, growth, breastfeeding, and stunting status features.
- Inspected missing values, duplicate records, feature distributions, outliers, and correlations.
- Removed duplicate records and handled numerical outliers using the Interquartile Range (IQR) method.
- Encoded categorical features using LabelEncoder and standardized features with StandardScaler.
- Prepared the dataset for classification by separating the features and stunting status target.
- Trained and compared Logistic Regression, Random Forest, and XGBoost models.
- Evaluated model performance using confusion matrix, classification report, Accuracy, Precision, Recall, and F1-Score.
- Selected Logistic Regression as the main model based on its Accuracy and Recall for identifying positive cases.
- Performed hyperparameter tuning experiments for Logistic Regression and XGBoost using GridSearchCV.
- Developed an interactive Streamlit dashboard for dataset exploration, filtering, and model comparison.